Document Classification in Multi-Type Ingestion Pipelines
Multiple classification methods work best together, catching errors that single approaches miss.
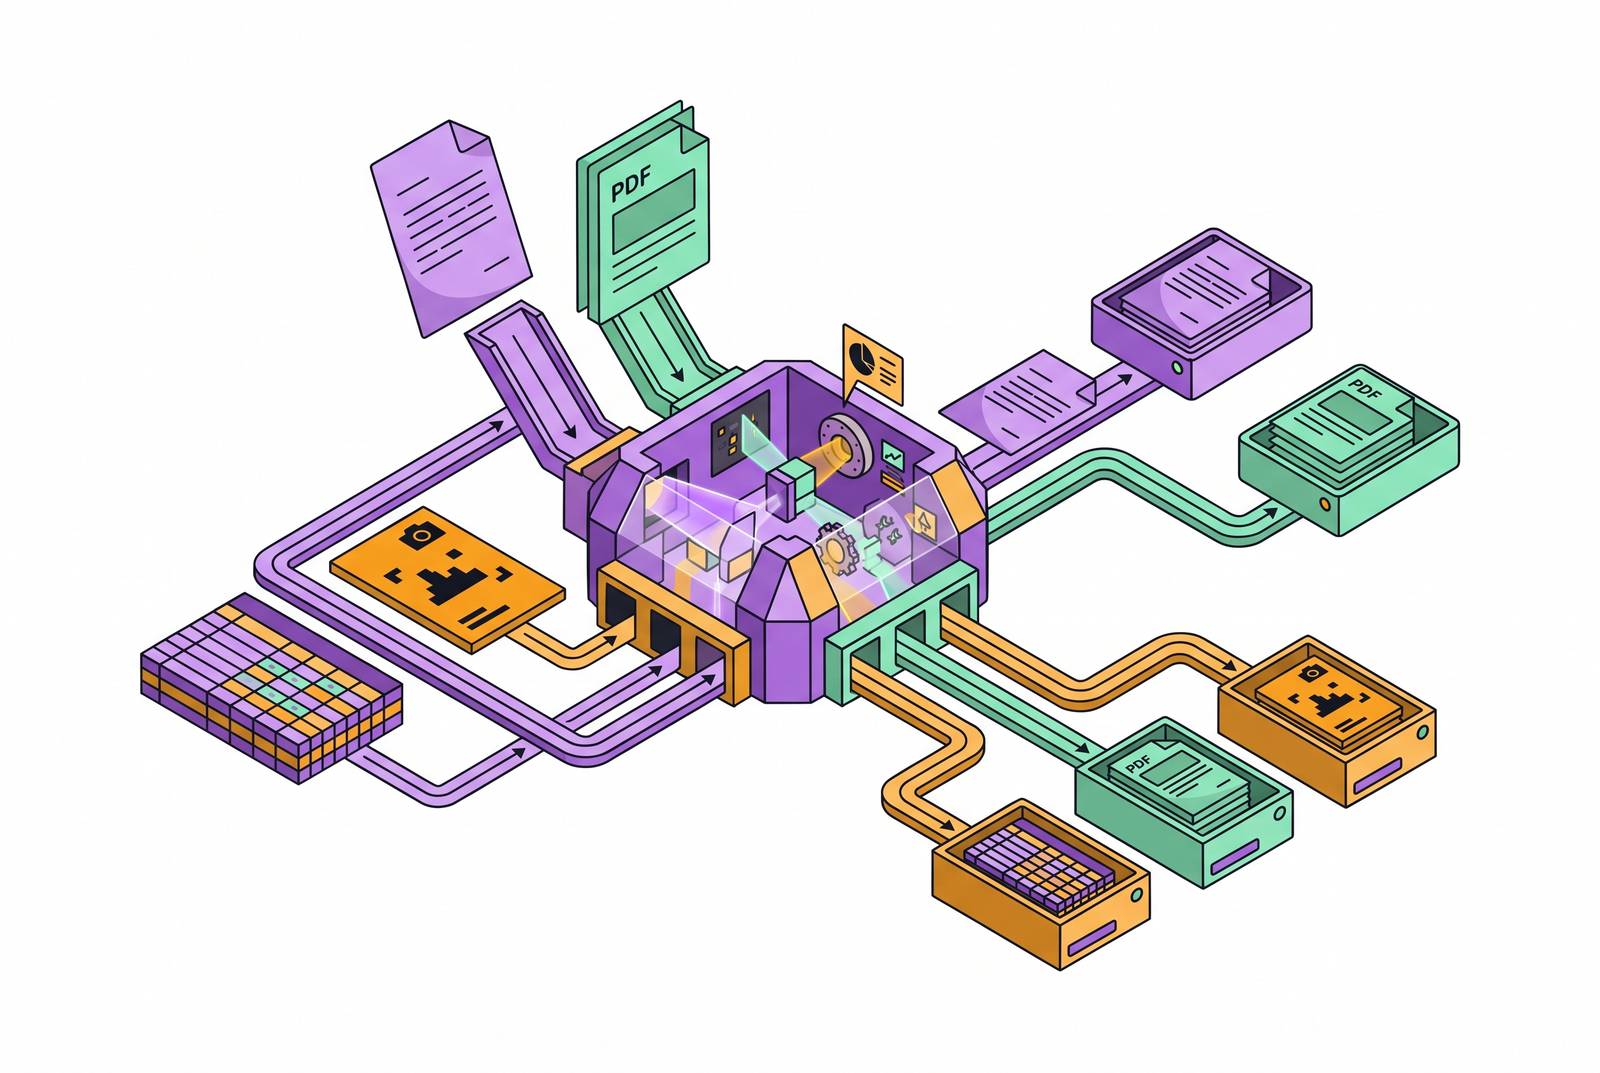
Classification is the first structural commitment a document ingestion system makes, and every downstream step depends on it being right. Once a document gets routed to a type, that routing decision sets which extraction schema applies, which validation rules check the output, and which confidence thresholds decide whether a human ever sees the result. Kungfu.ai's production microservice design states that classification has to route each document to the correct extraction pipeline before any field gets touched, because documents show up in all kinds of formats, multi-page TIFFs, scanned PDFs, photographs, and all of them need normalizing first, often with GPU-accelerated operations doing the heavy lifting.
A misclassified document doesn't just carry a wrong label. It gets pushed into an extraction schema built for an entirely different document type, so every field pulled out afterward gets measured against the wrong template from the start. An extraction error on a single field is recoverable. Someone catches it, corrects it, moves on. A classification error works differently: it corrupts the entire document's output at once, and it does so silently, because nothing in the pipeline is positioned to notice that the schema being applied doesn't match the document that arrived.
What a production multi-type ingestion pipeline looks like
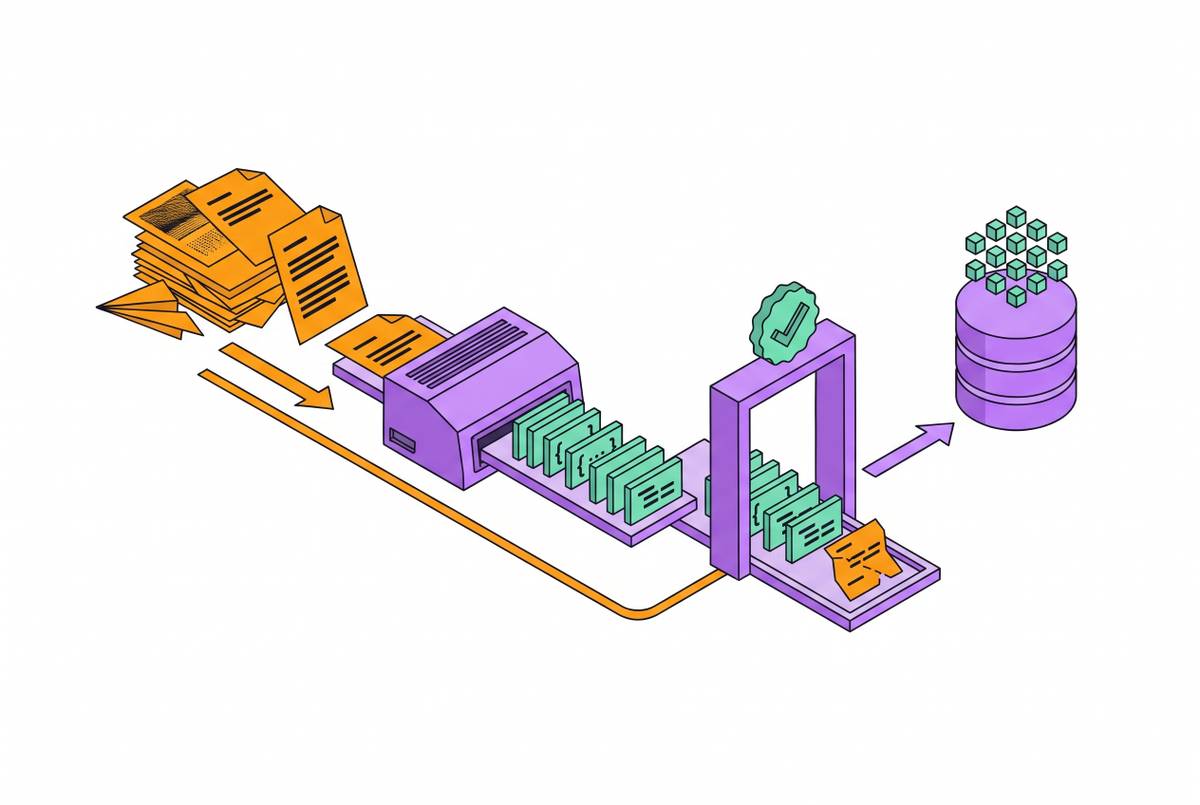
Production ingestion systems today are built as collections of specialized services, not single monolithic programs. Classification, OCR, parsing, extraction, and validation each run as a separate, independently scalable service, and classification is at the top of that chain: everything after it waits on its output. Kungfu.ai's architecture shows what this looks like concretely: three microservices running on Kubernetes, coordinated through a message queue, split into a Gateway, a set of Workers, and an Inference Service. The pipeline moves through hybrid classification, then OCR, then LLM-based field extraction, with GPU-bound inference steps kept separate from CPU-bound orchestration so each piece can scale on its own terms.
The MADP framework, described by Gosmar and Zenezini in a paper from May 2026, lays out the same dependency chain with five named agents working in sequence: Classificator, Splitter, Parser, Extraction, Validator. The order isn't arbitrary. The Splitter can't segment a document correctly until the Classificator has already figured out what type of document it's looking at, and the Parser can't pick the right layout strategy until the Splitter has done its job. Each agent's output is the next agent's starting assumption.
This pattern holds at much larger scale too. GPU-accelerated suites such as NV-Ingest take PDFs and office documents and turn them into structured JSON, pulling out text, tables, charts, and images as part of ingestion. MMORE, a framework out of EPFL, ETHZ, and Harvard published in September 2025, pushes this further, handling more than fifteen file types and running natively across multiple nodes and multiple compute accelerators. What's notable about MMORE is what the scale proves: adding more throughput and more file types tightens the dependency on correct classification, because more volume and more variety both mean more chances for the wrong document to land on the wrong path.
Classification at the Page Level: Hybrid Strategies and Trade-Offs
No single classification method wins across every document type a production system will encounter, which is why production systems lean on hybrid strategies that mix visual and text-based signals depending on what's reliable at the moment. Kungfu.ai's system runs on CLIP embeddings paired with a k-nearest-neighbor index, trained on representative page images, as its main classifier. That choice matters because it's a visual method: it doesn't depend on OCR output, so OCR noise can't degrade the classification decision itself.
Text-based classifiers built on BERT-family models work well when OCR output comes out clean. Layout-aware models, LayoutLM and the models that followed it, combine text, layout coordinates, and visual features together. End-to-end vision models like Donut skip OCR entirely and work straight from the image. Label Your Data's 2025 guide to document classification lays out the trade space simply: reach for BERT when the document is plain text, reach for LayoutLM when the structure on the page carries meaning.
A pipeline that assigned multiple classification probabilities to a document, instead of forcing it into a single category, saw accuracy improve by roughly forty percent. Vector embeddings, used to group similar documents into neighborhood clusters, cut misclassifications by a large margin on top of that. Forcing a document into one confident label when the evidence doesn't support that confidence is a design choice, and it costs real accuracy.
Classification also has to happen at the page level, not just the document level, because a single PDF submitted to a pipeline might contain an invoice, a remittance advice, and a purchase order stacked as consecutive pages. Each of those pages needs its own schema. Treating the whole file as one document type guarantees that at least some of those pages get extracted wrong.
Where classification fails in production
Classification failures in production are the predictable outcome of the gap between how a model performs on a clean benchmark and how real documents actually arrive. Label Your Data's guide names three blockers that cause failure before a classification model ever runs: OCR noise, layout shifts, and messy formats, and states that most document classification pipelines fail before they ever reach production for exactly these reasons.
The OCR failures themselves take specific, documented forms. Subscripts and superscripts get misread routinely, so m³ turns into m³3 on the page. Natural frequency notation gets garbled into raw LaTeX tokens, with exponent signs lost along the way. Entire sections of a document can vanish from the output without a trace, and the only way to catch that omission is a side-by-side comparison against the original. None of this looks like an error to the system processing it. When a frontier language model reads source material that's been corrupted this way, it generates confident, high-probability tokens about the noise itself, because the input failed, not the model.
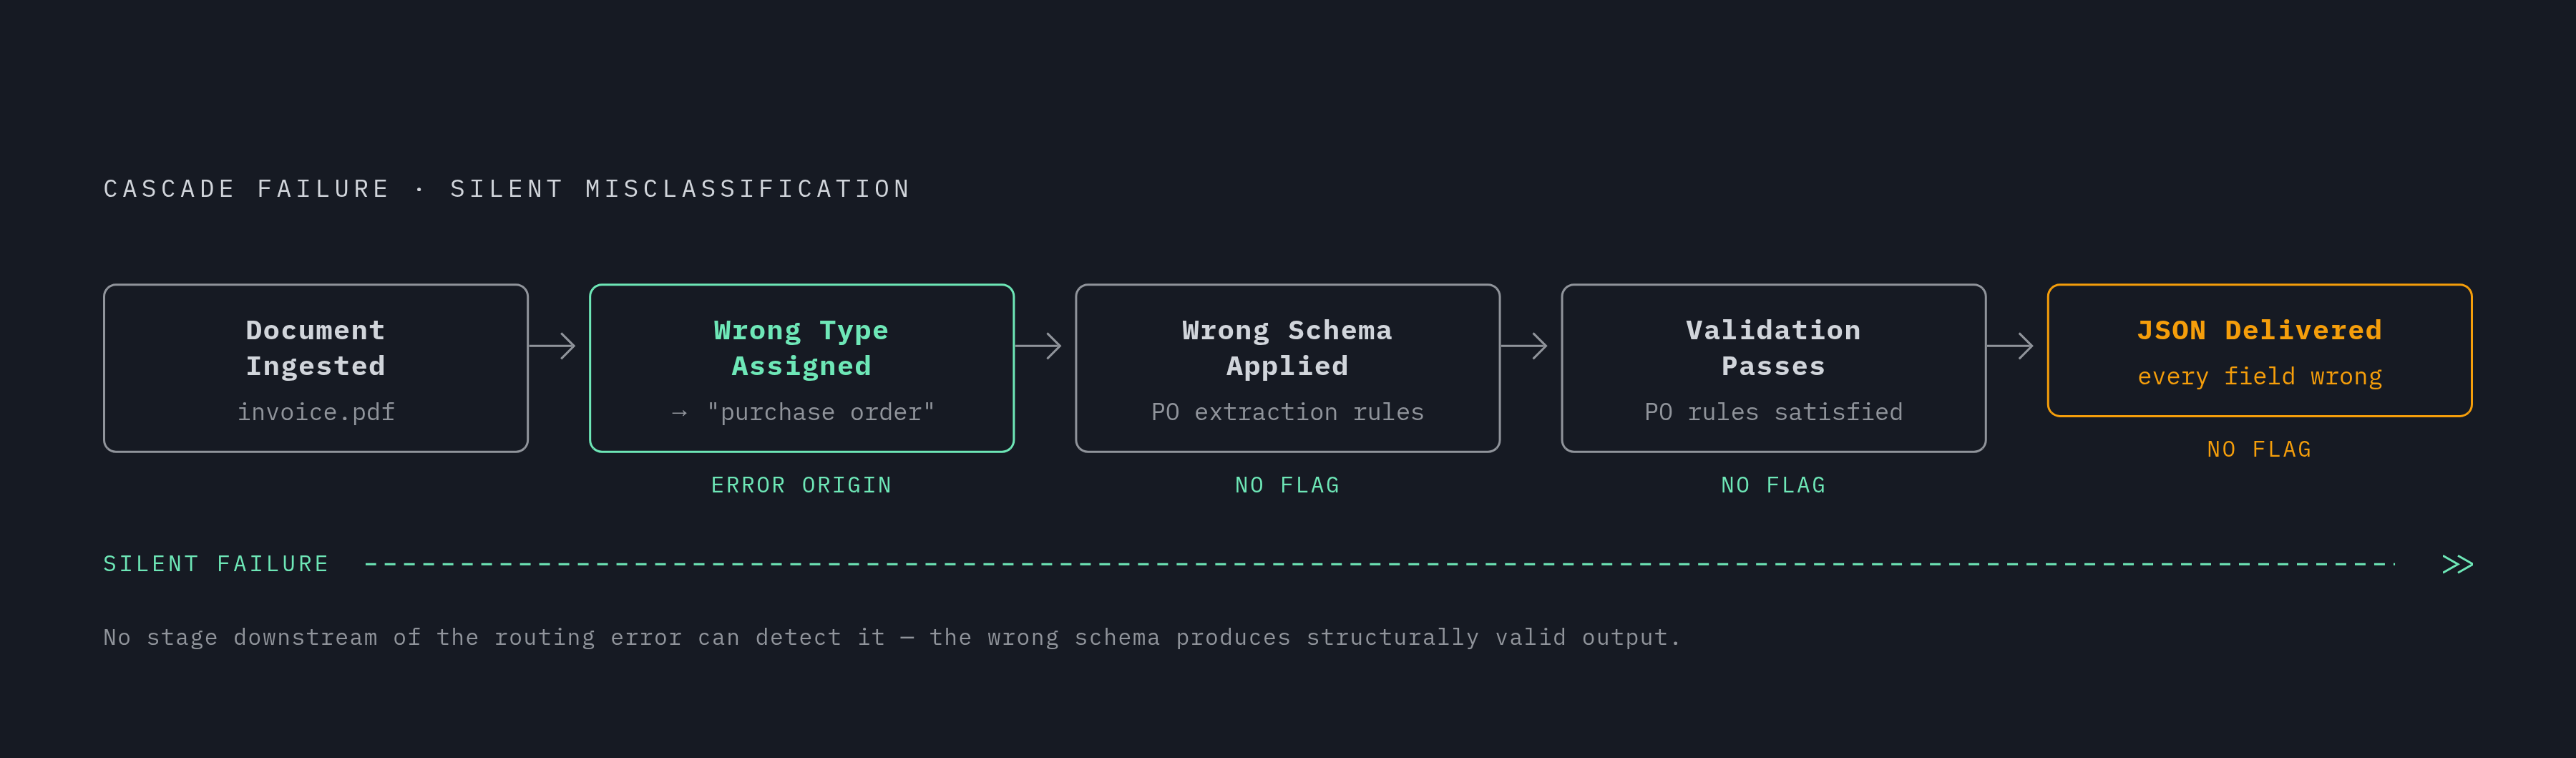
From there the cascade runs on rails. A document misclassified as type A gets routed to type A's extraction schema. That schema pulls out the fields defined for type A. Validation rules built for type A check the output and pass it. The result gets delivered as structured JSON, and every single field in it is wrong relative to what the document actually was, with nothing in the pipeline flagging that anything went off course. Kungfu.ai's paper states the structural reason this happens: classification determines which extraction pipeline gets applied, so the extraction pipeline itself has no independent way to detect that it was handed the wrong document type in the first place.
Table extraction makes this worse in a specific way. Merged cells, hierarchical headers, and values that continue across pages mean a single shifted header or one merged-cell error causes an agent to pull the wrong value while giving no sign that anything went wrong. In financial workflows, that's not a data quality nuisance, it's a compliance and audit risk.
Retrieval-augmented generation systems carry their own version of this failure. A table that gets flattened loses its row and column structure and turns into a meaningless run of numbers. When multi-column layouts get read straight across the page, sentences that were never meant to sit next to each other end up interleaved. Headers, footers, and figure captions bleed into the body text and dilute the resulting chunk's embedding. The retriever then surfaces the wrong chunk for a query, and the generation model answers from that corrupted context with full confidence.
ParseBench, cited in the Gosmar and Zenezini paper, tested fourteen parsing methods against a large corpus of enterprise pages across five capability dimensions, and found that no single parser dominates across all of them. That result matters because routing a document to the wrong parser is a systematic accuracy problem, built into the architecture, that no amount of downstream cleanup can fully undo.
How to measure whether a classifier is working in your document mix
A classifier's accuracy has to be measured against the actual document mix a pipeline receives in production, type by type, not against a clean benchmark dataset. A model that scores well on single-type PDFs in a lab setting can still fail systematically once it meets the multi-page, mixed-type submissions that occur on a live system.
Measuring this well means pulling a representative sample from the real production mix, including the worst cases, and checking accuracy per document type rather than relying on one aggregate number. An aggregate figure that looks strong can hide a minority document type getting misclassified consistently, and that minority type can easily be the one carrying a disproportionate share of high-value transactions.
Confidence calibration deserves separate attention. A confidence score is only useful if it actually means what it claims: a value flagged at a given confidence level should turn out correct at roughly that rate. Calibration quality differs by field type, with numeric fields tending to calibrate well and free-text fields showing overconfidence at high predicted probabilities. The research cites 0.85 as a representative confidence threshold: documents scoring below that line get routed to a manual review queue instead of passing straight downstream. That makes the confidence score a routing decision rather than a number attached to the output as metadata.
Scoring method matters just as much as the threshold itself. Exact match scoring checks for strict correctness, but relaxed match scoring accounts for the kind of variation OCR naturally introduces along with text normalization differences. Using exact match alone overstates how often the pipeline is failing on fields where OCR variation is the real cause. But relaxed match alone understates failure rates on fields where the extracted value is actually wrong, not just differently formatted. A sound evaluation framework runs both and treats the gap between them as information.
What a well-designed pipeline does when classification is uncertain
Routing uncertain documents to a human reviewer instead of pushing them downstream and hoping the schema fits is correct design. MADP builds this in directly: when a document fails validation or comes back with low confidence scores, the system sends it to human review. The MADP paper doesn't say whether this check happens at the classification stage, the parsing stage, or somewhere else, and it doesn't describe structured validation errors or best-effort extraction preservation in those exact terms.
MADP ran against 955 real-world documents through January 2026 and hit a 97.0% full-pipeline automation rate, so only three percent of documents needed a non-AI fallback. On the ablation subset tested, the full configuration, with Human-in-the-Loop supervision included, reached notably higher document-level accuracy than the configurations without it. Selective human intervention, used only where confidence or validation demands it, improves accuracy without requiring a human to check every single document.
Schema validation plays a parallel role to human review. Parsing LLM output against a Pydantic schema, one that defines exactly which fields are expected and what type each should be, is the standard pattern for catching problems before they travel further. When validation against that schema fails, the system has a concrete signal that something went wrong at classification or extraction, and it can route the document accordingly instead of passing malformed JSON downstream as if nothing happened.
MADP adds one more layer on top of human review: a mechanism called Prompt Fine Tuning with Feedback Inheritance, or PFTFI. It uses the corrections a human reviewer makes to refine how the system extracts data going forward, without retraining the underlying models. Each human review event, under this design, becomes a source of improvement for the system as a whole rather than a one-off fix applied to a single document.
Build vs. buy: what the classification complexity means for the make-or-procure decision
Everything laid out above changes what the build-versus-buy decision turns on: whether a team can keep absorbing the engineering work needed to maintain a classification layer that holds up against edge cases no demo ever shows.
Several costs tend to stay hidden until a system is already in production, and they tip the calculation against building in-house more often than teams expect. Teams typically budget for the extraction work and then discover that the human review application built around it takes more engineering effort than the extraction model itself. Four specific problems appear once a system is live, not at the demo stage: every extracted value needs to know its exact location on the source page, and that's brutal to retrofit once a system is already built without it. The human review interface, over time, tends to outgrow the AI work it was built to support. Code that was frozen to keep behavior stable breaks anyway when the underlying model provider updates its API. And a system that gets things right most of the time still needs a plan for the rest, because the fraction it gets wrong is exactly the fraction that does the most damage if nobody built a path for catching it.
Classification causes every one of these costs. A team that underestimates how much engineering goes into classification, confidence calibration, and human review routing is underestimating the single factor that determines whether the other 97 percent of documents get handled correctly at all.