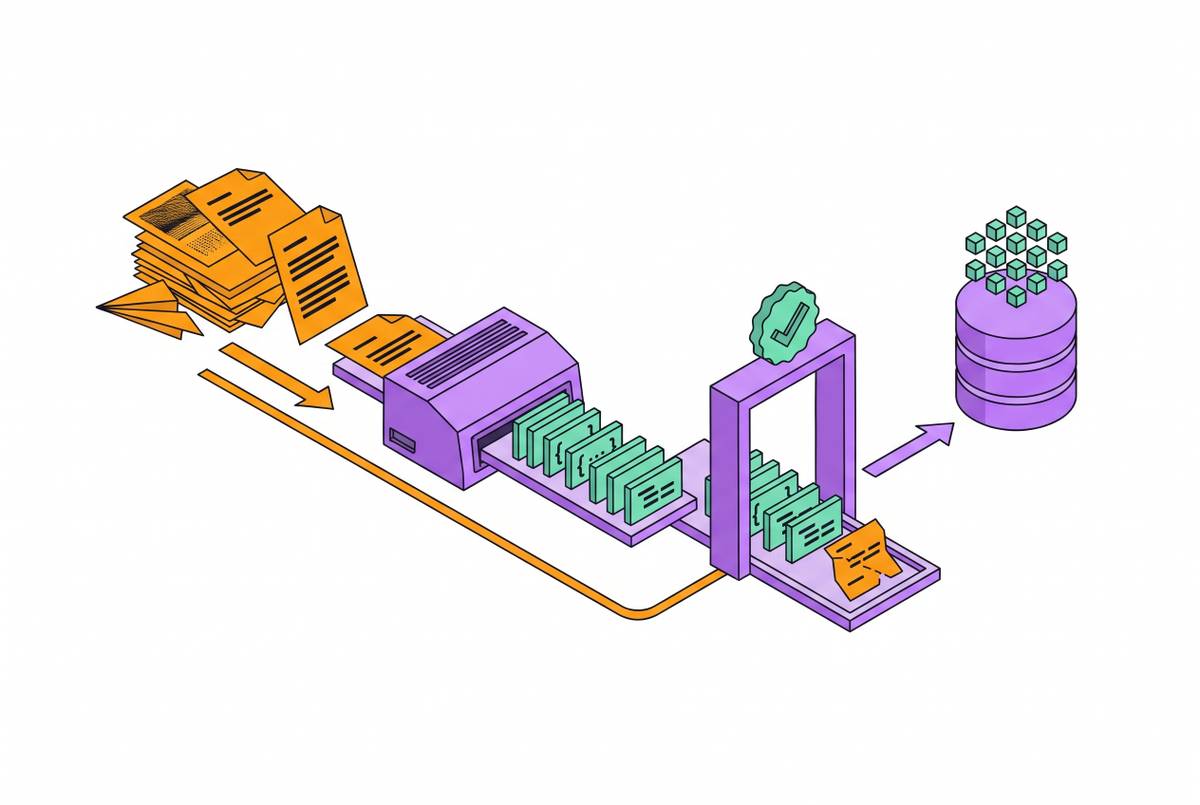
Structuring Raw Documents Into Validated JSON Before Vector Database Ingestion
Validate extracted data before ingestion to prevent retrieval failures.
Marcus Delacroix-Whitfield
Section
13 stories in Pipeline Architecture.
Validate extracted data before ingestion to prevent retrieval failures.
Extraction errors that enter the index become permanent evidence no model can repair.
Extraction quality sets your RAG floor before the LLM ever sees the evidence.
Reliable PDF extraction requires ground-truth testing and accuracy gates before any RAG indexing.
Silent failures in intake compound quietly across thousands of documents before anyone notices.
Agentic systems resolve extraction ambiguities themselves before routing documents to humans.
Pre-trained and fine-tuned models fail silently in production document work.
Automated extraction quality makes or breaks three-way matching accuracy.
How to prevent undetected errors from corrupting data downstream.
PDFs store tables as positioned text, not data structures, making extraction fragile.
Multiple classification methods work best together, catching errors that single approaches miss.
Merges, nesting, and missing grids make tables the document AI problem most vendors don't solve.
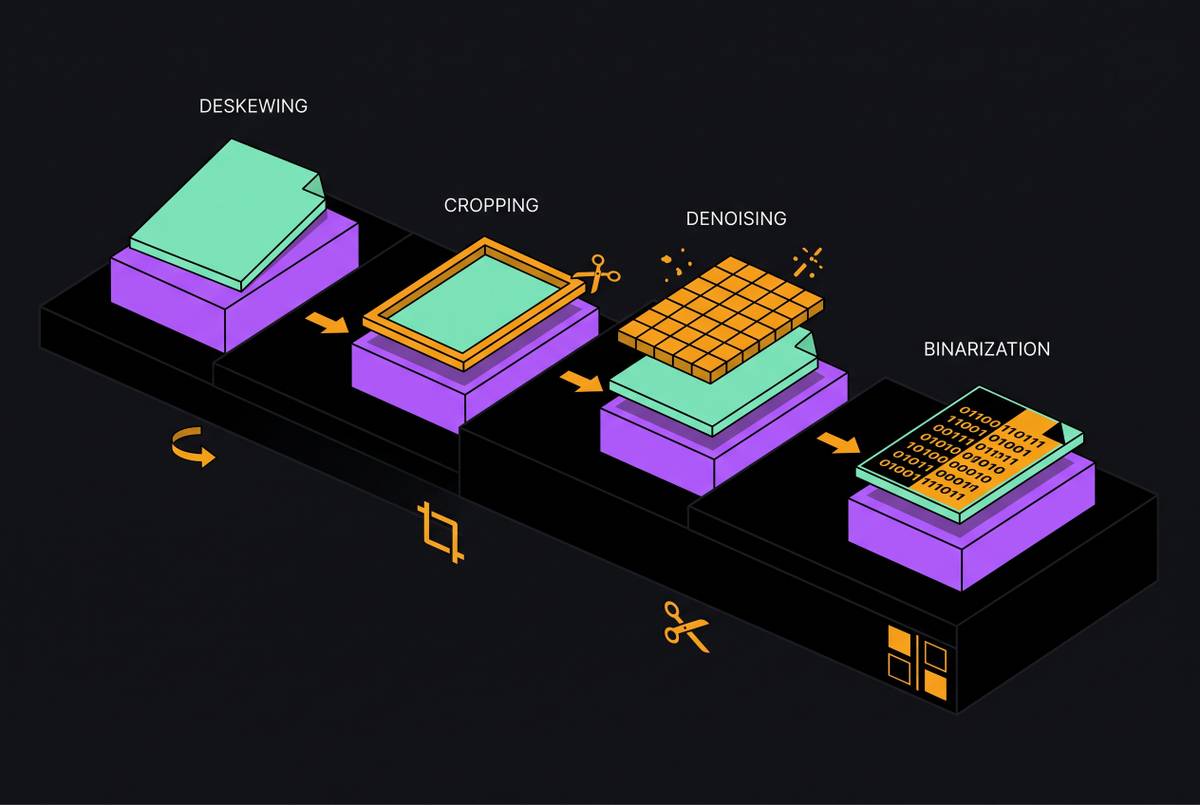
Sequence matters more than technique in document preprocessing for OCR accuracy.