SLA-Backed Accuracy Guarantees as an API Design Constraint for Production Extraction Pipelines
Field-level accuracy measured against latency and cost becomes your SLA design constraint.
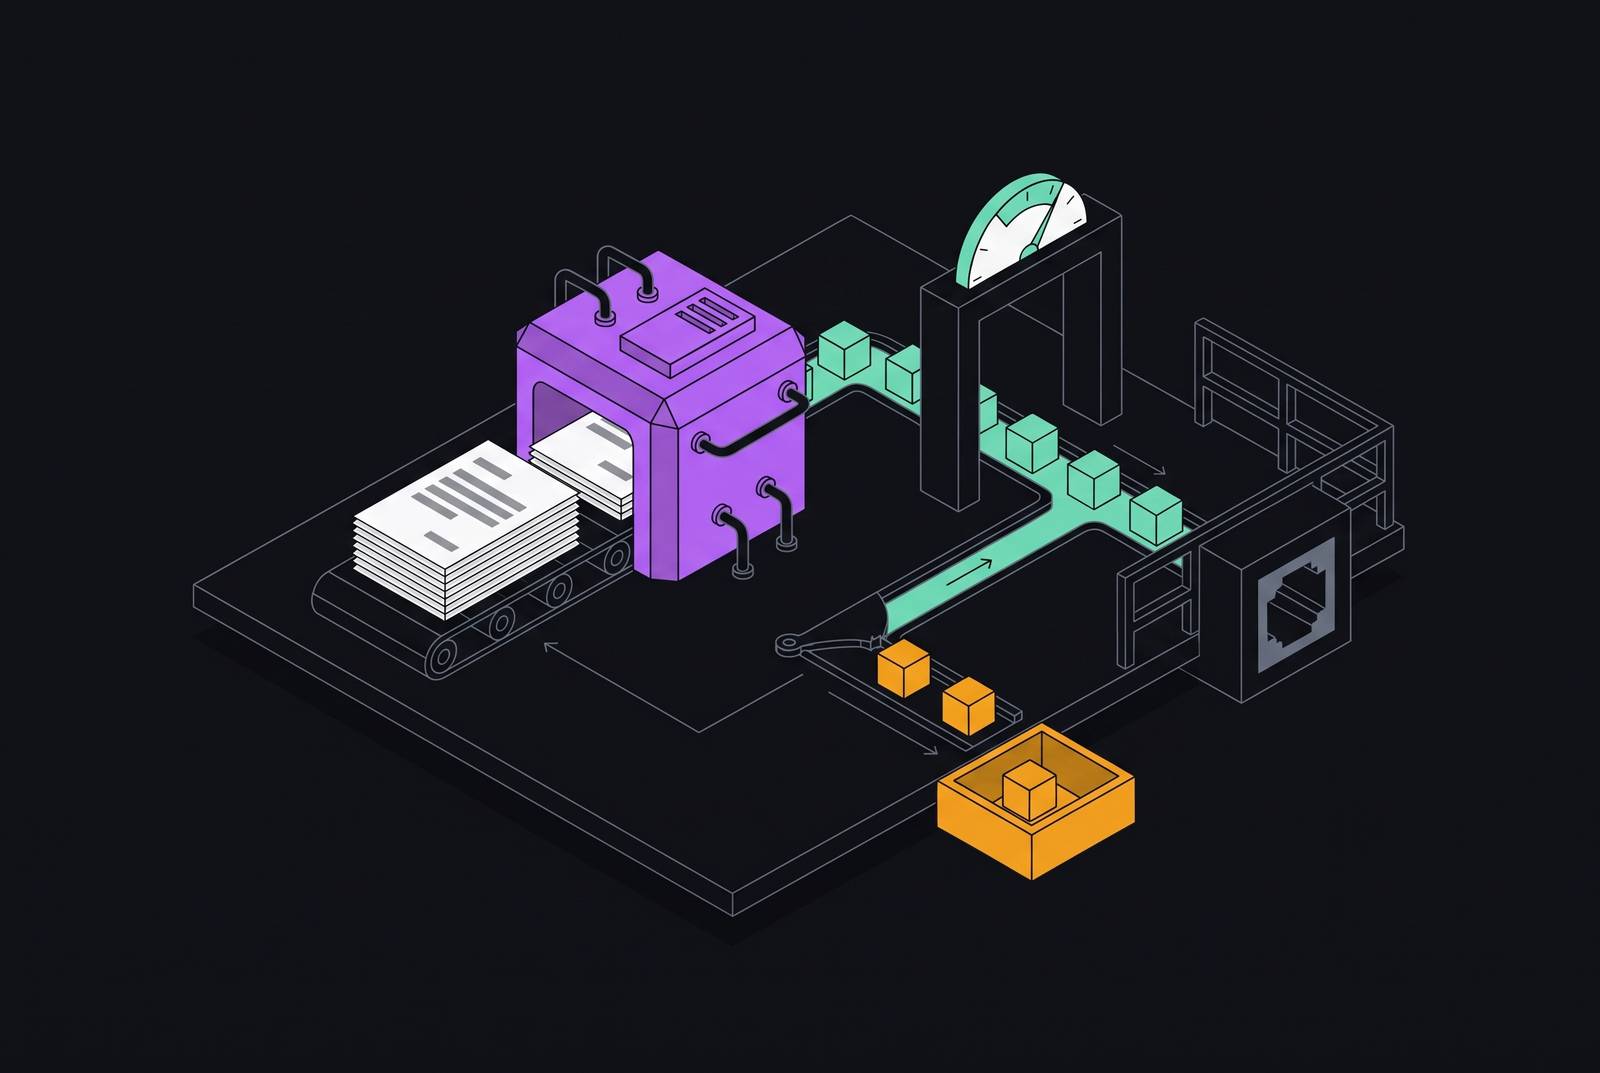
For production pipelines replacing another document-processing service, the useful comparison is not headline accuracy but contractual accuracy per field, measured against latency, cost, and governance needs. An SLA-backed accuracy guarantee is an API design constraint. It calls for evidence that measurement, confidence scoring, validation, and failure handling work together before results reach downstream systems.
Why a vendor accuracy number is not an engineering specification
A vendor’s overall accuracy percentage says too little to design around. It hides differences between field types, document layouts, and confidence bands. A provider can score well on invoice headers while struggling with line items, where table parsing creates downstream errors. Without those distinctions, the number is commercially useless as a specification, even if the underlying technology is capable.
Production extraction needs three separate SLA boundaries, covering latency, cost, and accuracy. None substitutes for the others. An accuracy figure that is not attached to a field, document type, and confidence band cannot set a routing threshold, a review queue depth, or a downstream processing rule. Likewise, fast processing does not show that results are correct, and a low price for processing says nothing about the work needed to catch mistakes.
A buyer’s tests before signing help show how well the system works at first, but leave open who is responsible afterward. Performance can degrade after the contract is signed. Without a contractual commitment and a remedy, that change leaves the customer holding the accuracy risk. The replacement for a headline number must therefore describe both what gets measured and what happens when the promised result is not delivered.
How per-field measurement changes what accuracy means
Field-level scoring assigns an independent correct or incorrect verdict to each extracted value, such as an invoice number, date, vendor name, or line-item unit price. These independent verdicts expose where the model fails. A model that handles headers well but struggles with line items needs different routing logic for those field types.
The John Hancock VLM study illustrates why the distinction is necessary. GPT-5 led the commercial pool on overall F1, while fine-tuned open-source VLMs exceeded all commercial systems in that evaluation. But Claude Sonnet 4.5 failed badly on the Date field in particular. An aggregate ranking conceals that particular weakness. The finding supports field-specific evaluation.
That evaluation needs an independent reference point. Ground truth means held-out, manually verified correct values. The study used a 750-document held-out pool with ground truth for Payee, Amount, Date, and Bank to produce per-field and per-error-mode breakdowns. A defensible evaluation needs this structure, with no required dataset size for every task.
Once accuracy is promised per field, internal measurement must use the same granularity. Without that measurement, the vendor cannot tell whether it keeps its promise. To turn that measurement into runtime decisions, the pipeline also needs field-level confidence scores. Those scores connect observed performance to the choice between automatic processing and further review.
What calibrated confidence scores actually require
A confidence score is useful only when higher confidence reliably predicts higher accuracy. How certain a model says it is does not prove that link. Calibration means comparing scores with what the model got right and wrong against ground truth. Without that comparison, a score cannot reliably separate fields safe to process automatically from fields that need review.
The difficulty is sharper in LLM-based extraction because a plausible answer may not appear in the document at all. Traditional OCR can misread an existing character, while a model can invent an entire value. Both can return high confidence. A credible routing signal therefore needs grounding in a source pixel region or text span, because grounded and ungrounded extractions have different correctness rates.
Pipelines that do not separate visual rendering from text-layer parsing are vulnerable to prompt injection through hidden text. A high score does not repair that exposure. Calibration needs a pipeline that can be trusted to handle source content.
When those conditions hold, confidence becomes an allocation tool. High-confidence results can proceed automatically while human review concentrates on the low-confidence tail, improving the effective accuracy of the pipeline without improving the model itself. The reverse is just as important. Uncalibrated scores scatter review effort.
How validation layers become mandatory once accuracy is a contractual term
Confidence shows which results need a closer look, but validation decides whether they can pass downstream. Once accuracy is part of the contract, that gate must be in place. Without it, confident errors can cascade before anyone discovers that the commitment was missed. The SLA needs an enforcement mechanism during processing as well as a report afterward.
Validation operates at several levels because each catches a different kind of error. Format checks establish whether a value is a valid date, currency amount, or VAT number. Cross-field checks test whether line items add up to the stated total. Domain rules check whether a tax rate is within the legal range for the declared jurisdiction. A plausible format alone proves very little.
A parser can drop a row from a multi-page table or put a valid amount in the wrong column without failing a format check. Cross-field and cross-row consistency checks address that gap. ParseBench measures structural fidelity, including merged cells, hierarchical headers, and cross-page continuity, within its Tables capability dimension. These structural failures are especially dangerous because the output can look usable while being factually wrong.
Validation also changes the order of commercial operations. In a pay-for-correctly-extracted-pages model, a page is billable only if all its fields pass validation, so the gate must run before billing. When automated checks cannot give a confident verdict, human review is the last tier of validation.
Failure modes that only appear in production, not in demos
A template extractor assigns meaning to text partly through where it appears, so a changed invoice layout can move values into the wrong fields without triggering an error. Successful extraction is not enough to detect this. The pipeline needs validation that can challenge the assigned meaning.
Reading order creates a different silent failure. A parser that reads left to right across both columns of a two-column document blends unrelated sentences into text that can remain syntactically plausible. The consuming system then receives the wrong meaning. This makes reading order an extraction requirement, even when downstream errors first appear to belong to another system.
Hard tables compound the problem through two-dimensional associations. Merged cells, spanning rows, and multi-page tables can produce output that looks valid but has missing rows or values under the wrong header. Cross-row consistency checks are necessary here. A shifted header can corrupt financial analysis without producing an obvious parsing error. Structural fidelity must be evaluated independently of whether the output resembles a table.
Non-determinism adds a separate requirement for audit records. The same document can produce slightly different outputs across LLM runs, so a pipeline must log model versions, parameters, and output per document to demonstrate reproducibility in regulated environments. Meanwhile, handwritten annotations on typed forms, insurance EOBs mixing tables with dense prose, and multi-language invoices stack independent failure modes. At thousands of documents per day, spot-checking cannot reliably expose these silent failures. Automated validation must handle the difficult tail.
How latency and throughput SLAs interact with accuracy commitments at scale
Accuracy checks consume time, and some documents need more checking than others. One pipeline-wide latency threshold hides that variation. A short invoice and a multi-page insurance claim need separate budgets because their processing demands differ. Using the same budget for both either wastes capacity on simple documents or leaves complex ones outside the promise.
Batching improves throughput and cuts the cost per document, but the added wait can push a document past its latency limit. Production at high volume therefore needs streaming or asynchronous processing. The measurement must match production conditions. Per-document-type p95 baselines belong against real traffic, with regression caught in CI before it reaches production, rather than thresholds taken from a single test batch or laptop benchmark.
Cold starts must also be distinguished from steady-state processing. First calls to an external API or a freshly loaded model can be orders of magnitude slower, so a baseline that mixes them indiscriminately cannot guide a steady-state SLA. Review adds a different delay. Documents sent to people need a separate latency commitment from automatically processed documents, or review queue depth distorts the combined p95 figure.
A non-deterministic pipeline may process a document again to clear a validation failure, which adds a delay that is hard to predict. In regulated environments, plans for latency must allow for the chance of that re-run. Because the probability depends on what the accuracy commitment requires the pipeline to reject or resolve, latency and accuracy cannot be designed separately.
The build-vs-buy decision when accuracy is load-bearing
The model does not necessarily account for the greatest expense of building. Teams often scope model selection, API integration, and basic extraction while leaving out the machinery that makes production accuracy defensible. That machinery includes ground-truth datasets, field-level measurement, confidence calibration, validation rule maintenance, and evaluation of new layouts. Every model update also means the team must test it again.
The Hancock study notes that frontier model lineups change on a quarterly cadence. Its durable contribution is therefore an evaluation-and-selection framework. Model choice remains an operating responsibility. A system that performed well at selection still needs reassessment as the available models and document population change.
Governance adds work that an API integration does not solve. HIPAA compliance, SOC 2 attestation, ISO 27001, and GDPR involve governance programs, dedicated expertise, and ongoing documentation. Sending medical records, contracts, or financial documents to a hosted API creates that question before the technical integration begins. For sensitive financial and personal information, zero data retention is the default that can be trusted, and teams that build it themselves must choose their infrastructure with care.
Building can win at very high volume when API costs are prohibitive, or where data cannot leave the organization’s infrastructure. Both cases still require continuous evaluation and operation of the selected model. For most teams facing volume, document variety, or compliance demands, maintaining the evaluation and governance machinery typically costs more than buying from a vendor with a contractual accuracy commitment. Scout from UC Berkeley illustrates how exploiting similarity between documents can reduce full-document frontier LLM processing. Cost efficiency remains an engineering problem.
What a per-field SLA commits a vendor to architecturally, and how to verify it
A real accuracy commitment comes with artifacts that a buyer can examine. The evaluation should begin with five questions. Does the vendor report how accurate it is per field or per document? Is there a held-out ground-truth dataset, and can the customer contribute documents? Are confidence scores calibrated and traceable to source regions? Are low-confidence results reviewed, flagged, or silently passed downstream? Is accuracy in the contract with a remedy clause?
Those answers establish whether the promise has operational support. The study’s selection framework maps a task profile, including quality threshold, latency budget, governance requirement, and expected volume, to an approach through filtering and total-cost minimization. That gives buyers a basis for comparing a vendor with an internal build. It avoids choosing on benchmark accuracy while ignoring the conditions under which the system must operate.
Governance needs inspectable records as well. Buyers should require per-run extraction logs containing model versions, field-level confidence scores, and output provenance to support demonstrable GDPR, HIPAA, and SOX compliance. These records serve as evidence within the wider compliance program. Claims of learning from corrections also need a documented feedback mechanism and a history of accuracy changes.
The dependency chain is the final test. Per-field commitments need field-level measurement against ground truth so that confidence can be calibrated. Confidence must connect to source evidence so that routing and validation can enforce the commitment at runtime. Failure handling resolves what validation cannot pass, while latency budgets account for that extra work. When correct-page billing depends on the validation gate, the same engineering chain determines both whether a result can be released and whether the vendor has earned payment.